Content providers (information sites, review sites, affiliate sites, lead generation sites, comparison sites) all rely on organic search engine traffic to sustain their operation. The leader of organic traffic, Google, introduced an algorithm change codenamed “Panda” that specifically targeted poor quality content.
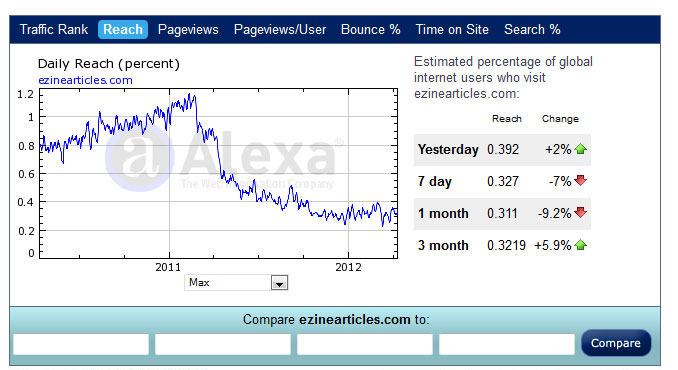
The result has been dramatic decreases in organic search traffic for certain websites, with drops ranging from 30% to 95% depending on the severity of the penalty. Companies such as Ezinearticles, have lost an approximate 66% of their traffic according to estimates provided by Alexa rankings.
In addition to a massive drop in revenue, many companies have been forced to restructure, downsize and adopt entirely new strategies to survive on the web. Thousands of jobs have been lost without any real answers.
The unstable environment is mainly caused by Google, which makes drastic changes that are kept secret from webmasters. “Poor quality content” therefore has no clear definition and is subjective to Google’s point of view on what content should be shown in the organic search results.
Previous algorithm changes have been easier to solve due to the rapid feedback mechanism provided by Google’s search engine. Previous to Panda, results could be seen within days of modifying a website, allowing search engine optimization experts to run a variety of tests to reverse engineer the algorithm.
With Panda, feedback is only provided when there are manual data refreshes. These refreshes tend to coincide with minor & major Panda updates which are usually 4 weeks apart. That means that search engine experts usually have to wait 4 weeks before seeing if their changes had any impact.
In order to solve the Panda algorithm, a new methodology is required. First, a sample of at least 100 websites is required in order to properly observe experiment and access the results. These websites should have a good distribution of sites that:
– Are affected by the Panda algorithm (Have seen a sudden drop in traffic after a Panda refresh)
– Are not affected by Panda (Have had consistent traffic before and after Panda)
– Have recovered from a Panda drop (Were penalized and bounced back)
The first step is to come up with multiple hypotheses that correlate to the data and can potentially explain the changes in search engine traffic based on the website and its ecosystem.
Putting yourself in the shoes of the engineers that wrote the code helps in this process.
Once you have a sufficient amount of hypothesis to test, you should execute all the changes on a wide variety of sites that have been affected by Panda. In order to accelerate the process, I recommend working with a team and doing multiple tests across a range of Panda-penalized websites.
Because results are only seen once a month (approximately), this speeds up the process tremendously.
After each Panda update, it’s important to note increases, decreases or lack of change on website traffic. Concentrate on the sites that have seen change and note the specific changes made to these websites.
In addition to internal testing, it’s important to seek out the reports of other webmasters that have recovered after each update. These recoveries often provide clues and lead to new experiments that you can run on your websites.
Don’t get discouraged if the first 20 experiments yield little-to-no results. By process of elimination, you can slowly adjust every aspect of a site to see if the changes yield results.
Theorize, create experiments, test, record results. Repeat.
In the event that you do succeed in a recovery, note the data and record the changes made to produce the change. This will provide clues to which experiments work and which don’t. The first recovery will help point you in the correct direction, and once you have such a recovery, your task should be to repeat it on a wide range of Panda-affected website.
At this point, you’re likely to see very interesting results that might be slightly confusing. The trick is to find general trends instead of absolutes.
For example, not all websites ranking for a keyword will have the keyword in the title… but most will.
Similarly with Panda, not all websites being penalized will have a certain element… but most will.
Panda does not penalize sites for only one reason, but instead for a combination of reasons. Using trends instead of absolutes will help you figure out these elements.
The first recovery will lead to many theories as to: “why” it recovered and it will be important to test all of these in order to accomplish your second recovery.
Once you have succeeded in a second Panda recovery, trends should start to become clear and you should be able to narrow down the recovery to a limited set of theories. Once again, noting the data, repeating the process and repeating your experiments on another set of Panda-affected websites will allow you to refine the recovery process.
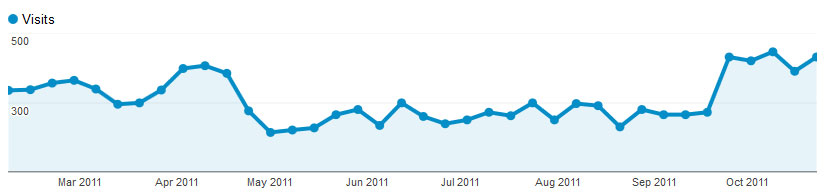
It’s important to note that during the second recovery, you are likely to have many sites that “don’t” recover. This data is equally important and will help you understand why the successes occurred.
Repeat your experiments until you are able to find a method that consistently recovers websites. A clear theory explaining why some sites recovered and some didn’t (in the second tests) should emerge.
After the third or fourth recovery, you should be able to explain the changes with relative ease. You should go over a list of Panda-penalized & Panda-free websites to confirm your data.
At this point you should have a theory that works with all websites and a method to recover websites from Panda.
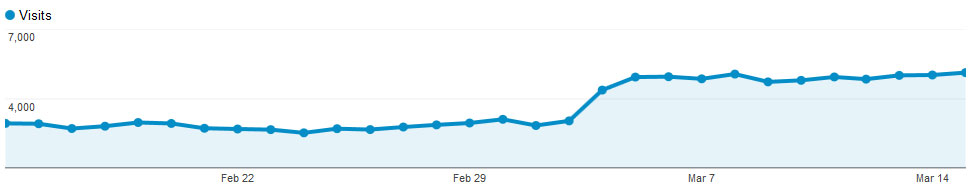
As previously stated, this experimentation requires a team, a large set of websites and over a year of time. The results of all this experimentation, along with the theory and repeatable method to recover sites from Panda penalties is now available from Eric Lancheres in a program called Panda Breakthrough.
The program includes all the fruits of the research, which includes an explanation to why certain websites have been penalized by Panda, the elements that have been proven to impact recoveries, the repeatable method used to recover websites of every size, case studies and proof.
It specifically addresses large scale information sites, medium scale information sites, e-commerce sites, review sites, affiliate sites and lead generation sites. Specific solutions are outlined for each type of site.
For more information, sign up for a live Webinar on recovering from Google Panda by Eric Lancheres.
Acquire the program today at https://www.pandabreakthrough.com/replay/ to recover from a Panda penalty and Panda-Proof it for the future.